FROM THE BOOKSHELF / A PAGE TO KEEP
GitHub Archived 11,000 of Its Own Repos. Cleanup Was the Side Effect.
Published on 2026-07-09
GitHub had 14,000+ internal repos and most had no owner — a real problem when a leaked secret needs rotating and nobody knows who to call. Here's how they made ownership a queryable, enforced property, the two production incidents that reshaped the design, and a reusable playbook.
GitHub's primary internal organization holds more than 14,000 repositories. As of early 2025, over 11,000 of them were still active — and most had no idea who owned them (GitHub Blog, July 2026). Not a vague "the docs team, probably." No owner at all. No name to ping, no team to page.
That sounds like a housekeeping annoyance until a secret leaks.
During GitHub's secret scanning cleanup, engineers could detect an exposed credential and technically rotate it. But rotating a secret without knowing who depends on the repository is how you take down a production service on a Tuesday afternoon. So before touching anything, someone had to answer a basic question: who owns this? For thousands of repos, the honest answer was a shrug.
A repository nobody owns isn't clutter. It's a security phone that rings with no one on the other end.
Why "check the README and ask Slack" doesn't scale
GitHub already tracked ownership — for services. Their internal Service Catalog mapped each deployed service to its repository, its team, its on-call rotation, its exec sponsor. Rich metadata, exactly what you want for incident response.
The catch was the direction of the arrow. The relationship ran service → repository. Start from a service, you find the repo and its owners. Start from a repository, and you're stuck reversing a lookup that only works if the repo backed a catalogued service in the first place.
Most repositories don't. Team repos, docs repos, internal tools, one-off projects, personal experiments — none of them show up in a service catalog. For every one of those, finding the owner meant reading commit history, skimming the README, guessing from the repo name, or asking around in Slack and hoping someone recognized it.
That works once. It does not work when a security workflow fans out across 11,000 repos at the same time. Manual archaeology becomes the bottleneck, and the bottleneck sits directly between "we found a leaked secret" and "we fixed it." The problem was never tidiness. Ownership was simply never a property you could query — it was tribal knowledge, and tribal knowledge doesn't answer a page at 2 a.m.
The fix: make ownership something you can query
GitHub's answer was to stop treating ownership as metadata that lives in someone's head and make it a first-class, org-wide property of every repository. They used GitHub custom properties and created two fields.
ownership-type took one of three values: Service Catalog, Hubber Handle (a Hubber is a GitHub employee), or Team. Those three cover the real shape of repo ownership — a repo belongs to a service with a lifecycle, a team like a shared docs repo, or a single person running an experiment.
ownership-name was a text field with light validation. Their GitHub App checked every value: employee handles against actual org membership, teams against existence plus a minimum of two members, Service Catalog entries against the catalog itself. Formatting was deliberately forgiving — type @my-team instead of my-team and it still took it. The design bet was to make adding ownership frictionless and lean on validation to catch the things that actually matter: nonexistent teams, former employees, decommissioned services.
Then they front-loaded the easy wins. A periodic sync pulled from Service Catalog and auto-populated ownership for roughly 1,500 service-backed repos before anyone had to lift a finger. That left the team repos, docs, prototypes, and personal projects for humans to claim.
Enforcement ran on a GitHub App backed by a Kubernetes CronJob — not a simple Actions workflow, because the logic needed to reach the Service Catalog, the GitHub API, and several internal systems at once. Any repo without ownership got an issue opened on it warning of archival in 30 days. Claim it and set an owner, the issue closes. Ignore it, and after the grace period the repo gets archived: read-only, Actions stopped, nothing deleted, and a one-click path to unarchive. Reversible by design, which is what let them apply it broadly instead of litigating every edge case.
Where it broke
The rollout was mostly smooth. Two incidents were where the actual lessons lived.
The first run was scheduled for a Saturday morning, on the theory that nobody would be watching. At a globally distributed company, someone is always watching. Issues lit up across the org and people flooded Slack asking why their repo was suddenly marked for archival.
Then the archiving caused a real page. One archived repo had been wired up so Datadog could open issues in it as part of a monitoring workflow. Archive the repo, Datadog can't create the issue, internal monitoring notices, and the owning team gets paged. The deeper miss underneath it: the ownership warnings were landing in repositories but not reaching people. GitHub fixed that by @-mentioning repo administrators and, as a fallback, assigning every user with write access. The warning could no longer be buried.
The second incident was quieter and more dangerous. GitHub had built resilience against a Service Catalog outage but not against the catalog returning stale or corrupted data. Bad data could convince the app that a batch of repos had lost their catalog entries when they hadn't — and then mass-archive repos with perfectly valid owners.
Their guardrail was a low water mark. Before acting, each run tallied how many archives and issues it was about to perform. Cross a conservative threshold and the job bails out entirely, firing a Datadog alert instead of doing the damage. If the catalog was unreachable, it skipped catalog validation and only acted on what it could independently verify. Neither the low water mark nor the @-mention fallback was in the original design. Both came from things breaking in production.

What actually made it stick
Hitting 100% coverage is worthless if it drifts back to 60% in six months, so the real work was keeping it there. Ownership properties became mandatory in every repository creation path — the creation page, internal tooling, automation. You cannot make a repo at GitHub now without declaring who owns it. And once the initial cleanup settled, they tightened the enforcement loop from 30 days to one hour. A repo that slips through or loses its owner gets flagged almost immediately, not next month.
They also designed around how each ownership type decays. Service Catalog entries follow the service lifecycle — deprecate the service, the repo archives with it, as intended. Teams stay stable as long as they have members. Individual handles go invalid when someone leaves, which usually means their personal repos should archive anyway. The rule that falls out of this is worth stealing: anything important enough to outlast one person should be owned by a team or a service, never an individual.
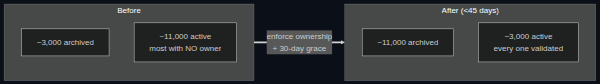
The numbers landed at roughly 3,000 active repositories and 11,000 archived, up from about 3,000 archived at the start — the whole thing under 45 days from that ill-advised Saturday run to steady state. Some of the archived repos hadn't seen a commit since 2008: dead experiments, finished hackathon projects, one-person prototypes long abandoned. Every active repo now has a validated owner, or it gets archived.
If you want to run the same play on your own org, the shape is straightforward:
- Define your ownership taxonomy. Services, teams, individuals worked for GitHub. Your categories might differ.
- Create org-level custom properties — a single-select
ownership-typeand a textownership-name— so ownership is queryable through the API, not buried in files. - Sync from an existing catalog first. Auto-populating what you already track gets you meaningful coverage before you ask anyone to do manual work.
- Enforce at creation time so the inventory stays clean going forward, and run a grace-period workflow for the backlog: open issues with a deadline, then archive the unclaimed. Archiving is reversible, so it's a safe default.
- Build guardrails before you trust the automation. Assume your data sources will occasionally lie and your notifications will sometimes vanish. And don't kick off your first enforcement run on a Saturday.
The cleanup — 11,000 repos archived, the active inventory finally reflecting reality — grabs the headline. But it was the byproduct. The point was that when the next secret leaks, someone knows exactly whose phone to ring.